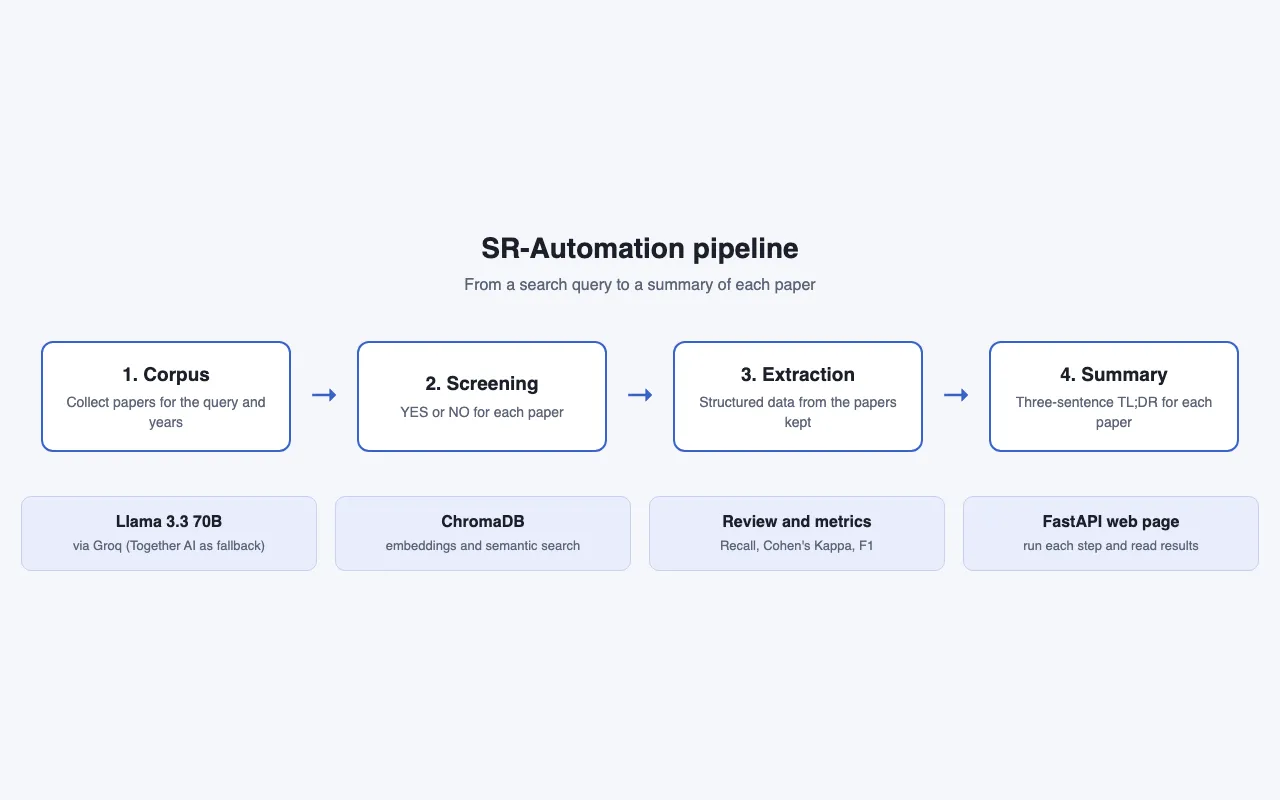
An LLM pipeline that screens, extracts and summarizes papers for systematic reviews.
StackPython, Llama 3.3 70B (Groq), ChromaDB, FastAPI, scikit-learn
Why I built it
This is the code of my master's dissertation in software engineering. A systematic review means reading hundreds of papers by hand. The project tests how far an LLM can do the first steps, and how to check its answers against a human gold standard.
Goals
- Collect papers for a query and a range of years
- Screen each paper with a YES or NO answer
- Extract structured data from the papers kept
- Write a three-sentence summary for each paper
- Measure recall, precision, F1 and Cohen's Kappa against a human review
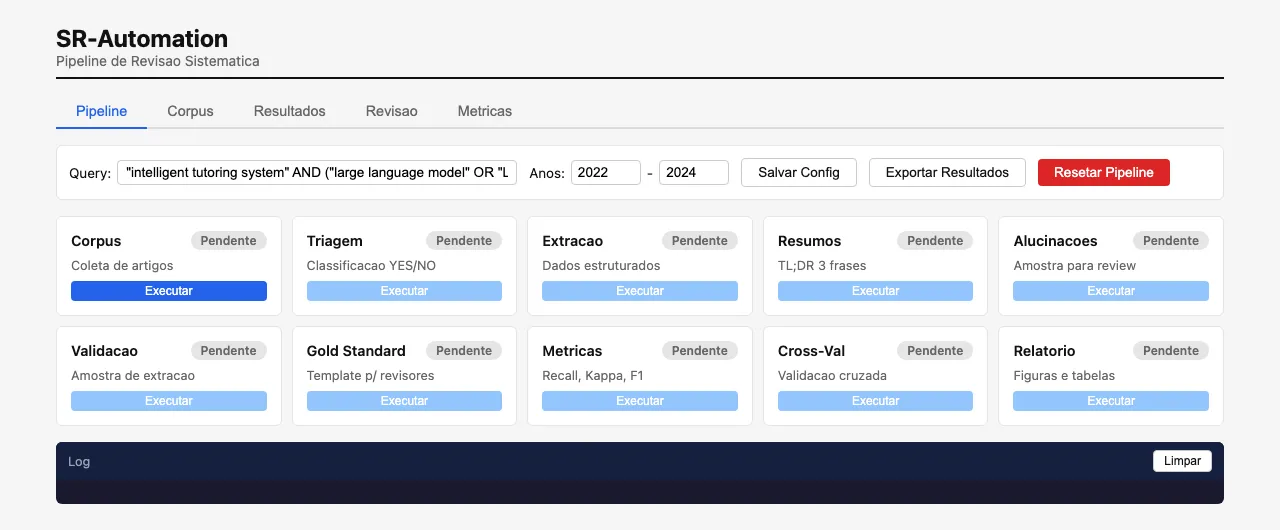
Screenshots